Service · Custom data extraction
Web scraping service, custom data on request
A web scraping service for teams that want the data, not the scrapers. You name the sources, the fields and the cadence; we run the extraction on our own collectors and proxy network and deliver CSV, JSON or an API feed, with the source on every row. On our five pilots, a free sample arrives within 24 hours.
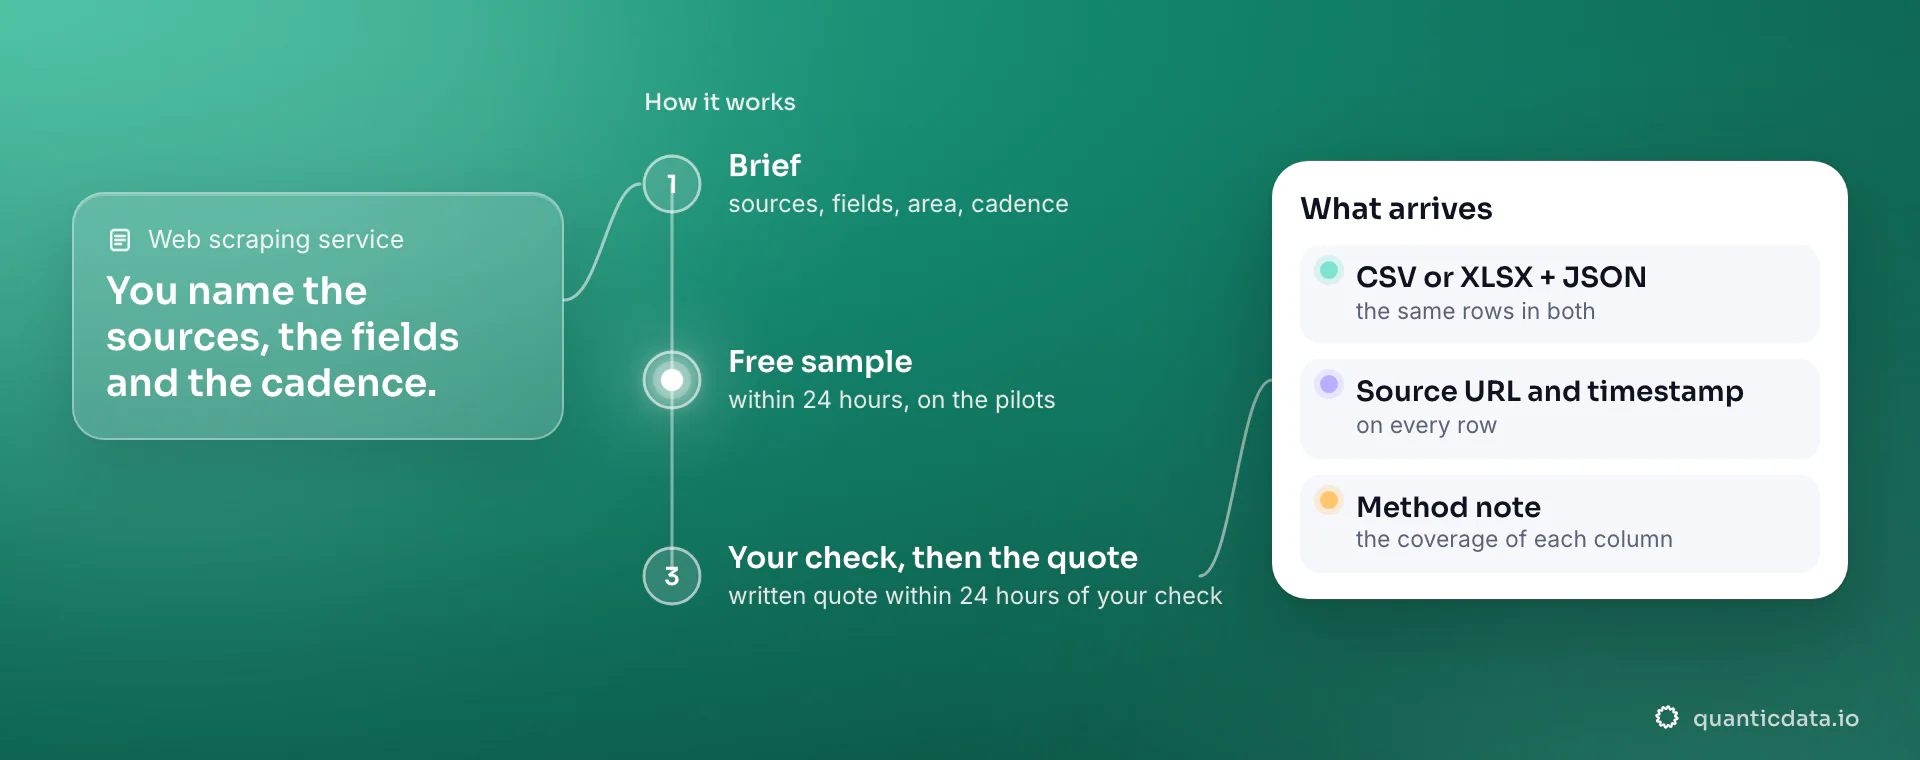
How it works
Brief, free sample, then the data.
- Brief. Tell us the sources, the fields, the area and how often, in your own words. A spreadsheet of SKUs, a list of properties, a category and a province is enough: you do not need to write a specification.
- Free sample. On the five ready-made pilots a real extract arrives within 24 hours: 50 rows for a list, one full run for a monitor, one week for a competition set, built with the same collectors as the final job. On other briefs, the sample and its acceptance criteria are agreed in the scope.
- Your check, then the quote. You verify a handful of rows against the live source. On the pilots a written quote follows within 24 hours of your check, and the run starts when you say so.
A pilot request gets a reply within 24 hours. The pass criterion of each pilot is written down before it starts, and the sample has to meet it: see the web data pilot.
What you get
Files you can trace back to the page.
| Part | What it is |
|---|---|
| Files | CSV or XLSX, plus the same rows as JSON |
| Provenance | The source URL and the timestamp on every row |
| Method note | What was included and what was excluded, and the coverage of each column measured on your data, not on the best rows |
| Status column | When something is not found, the row says so instead of leaving a blank cell |
| Run ids | Every run is stored under your account, so the same job can be repeated |
After the first delivery you choose: stop, with the files yours to keep; a scheduled feed at the cadence you pick, sent by email or pulled from the API with your own key; or run the same collectors yourself from the dashboard. Nothing renews by itself.
Sources we already cover
103 ready-made collectors, by category.
A brief can use any of them, and any other public web page: the web scraping API turns a URL into Markdown or JSON when no collector fits. Every collector has its own page with the fields it returns and its price per result: all collectors.
Five ready-made pilots
Jobs we have already run, in seven days.
| Pilot, and who it is for | What arrives in 7 days |
|---|---|
| Competitor price monitoring E-commerce retailers and brands | Your SKUs matched on the marketplaces you sell on, re-checked every day, plus a delta file of every price change |
| Hotel competition set Hotels and revenue managers | The lowest public rates on Google Hotels and on Booking for up to six competitors and two stay windows, one CSV a week |
| B2B leads by province Companies selling to local businesses | Every business of one category in one province, with the address confirmed on two sources, phone, website and published email |
| Review monitoring Multi-location brands and agencies | Every new Google review of the week with rating, text, date and owner reply, plus Trustpilot, Amazon and App Store |
| Property listings monitoring Agencies, investors, proptech | New, changed and removed listings in a city or set of areas, every day, from the portals that matter there |
A brief that is none of these starts the same way: describe it and choose "Something else" on the pilot form, or send it with the enterprise form.
What we collect
Public pages, businesses, and the platform rules.
We collect public web pages. Sources that require a login are out of scope, and so are personal data of consumers: lead work returns businesses and professionals at their business address, never private individuals. When a platform forbids a use, we say so in the sample instead of pretending.
What you may do with the data depends on the country and the use: see web scraping law in the US and in Europe.
For procurement
What your team can review before the first order.
Data Processing Agreement. The DPA sets roles, data categories and audit rights (section 9). It is published at /dpa/.
Sub-processors. Categories of sub-processors, with purpose and location, are published at /subprocessors/. The named list is sent under a DPA on request.
Billing agreement. For card charges, applicable taxes such as VAT are added where required and shown on the invoice. See /billing-agreement/.
Acceptable Use Policy. What is allowed and what is not, in one page: /aup/.
KYC and Sanctions Policy. When we ask for identity checks, including for unusually large orders: /kyc/.
Do it yourself instead
The same collectors, self-serve.
If your team would rather run the jobs, the same collectors work from the dashboard or the API, billed per delivered result, with $2 of free usage every month: collector pricing. Quantic AI turns a prompt into a dataset on its own.
How a brief becomes a schema, with the fields, the sample checks and the delivery format agreed up front, is described on custom datasets.
Before you send a brief
Questions teams ask
How much does a web scraping service cost?
There is no list price for a commissioned job. On the pilots the sample is free, and after your check a written quote arrives within 24 hours, in the unit that fits the job: per row for lists, per property per week for competition sets, per location per week for reviews, per run for daily monitors. The collectors themselves are priced per result on the collector pricing page.
How long does it take?
A pilot runs seven days from the moment we have your input, after a free sample that arrives within 24 hours. Weekly jobs, like a hotel competition set, deliver their first file before the following Monday.
Can you scrape a site that is not in your catalog?
Yes, if its pages are public. The 103 collectors of the catalog cover the common sources, and any other public web page can be part of a brief. Sources that require a login, or that hold personal data of consumers, are out of scope.
How is the data delivered?
As CSV or XLSX plus the same rows as JSON, with the source URL and the timestamp on every row. For a recurring job you choose the cadence and receive the files by email, or pull them from the API with your own key.
Is web scraping legal?
It depends on the country, the data and what you do with it: the posts on web scraping law in the US and in Europe go through the rules. We only collect public pages, never behind a login and never personal data of consumers, and when a platform forbids a use we say so in the sample.
Can I run the scraping myself instead?
Yes. The same collectors run self-serve from the dashboard or the API, billed per delivered result with $2 of free usage every month, and Quantic AI turns a prompt into a dataset by itself. The service is for teams that want the finished file.
Send your brief.
On the pilots, a free sample within 24 hours and a written quote within 24 hours of your check. The DPA and the sub-processor categories are published.