Collectors · Finance & crypto
SEC EDGAR API in Python
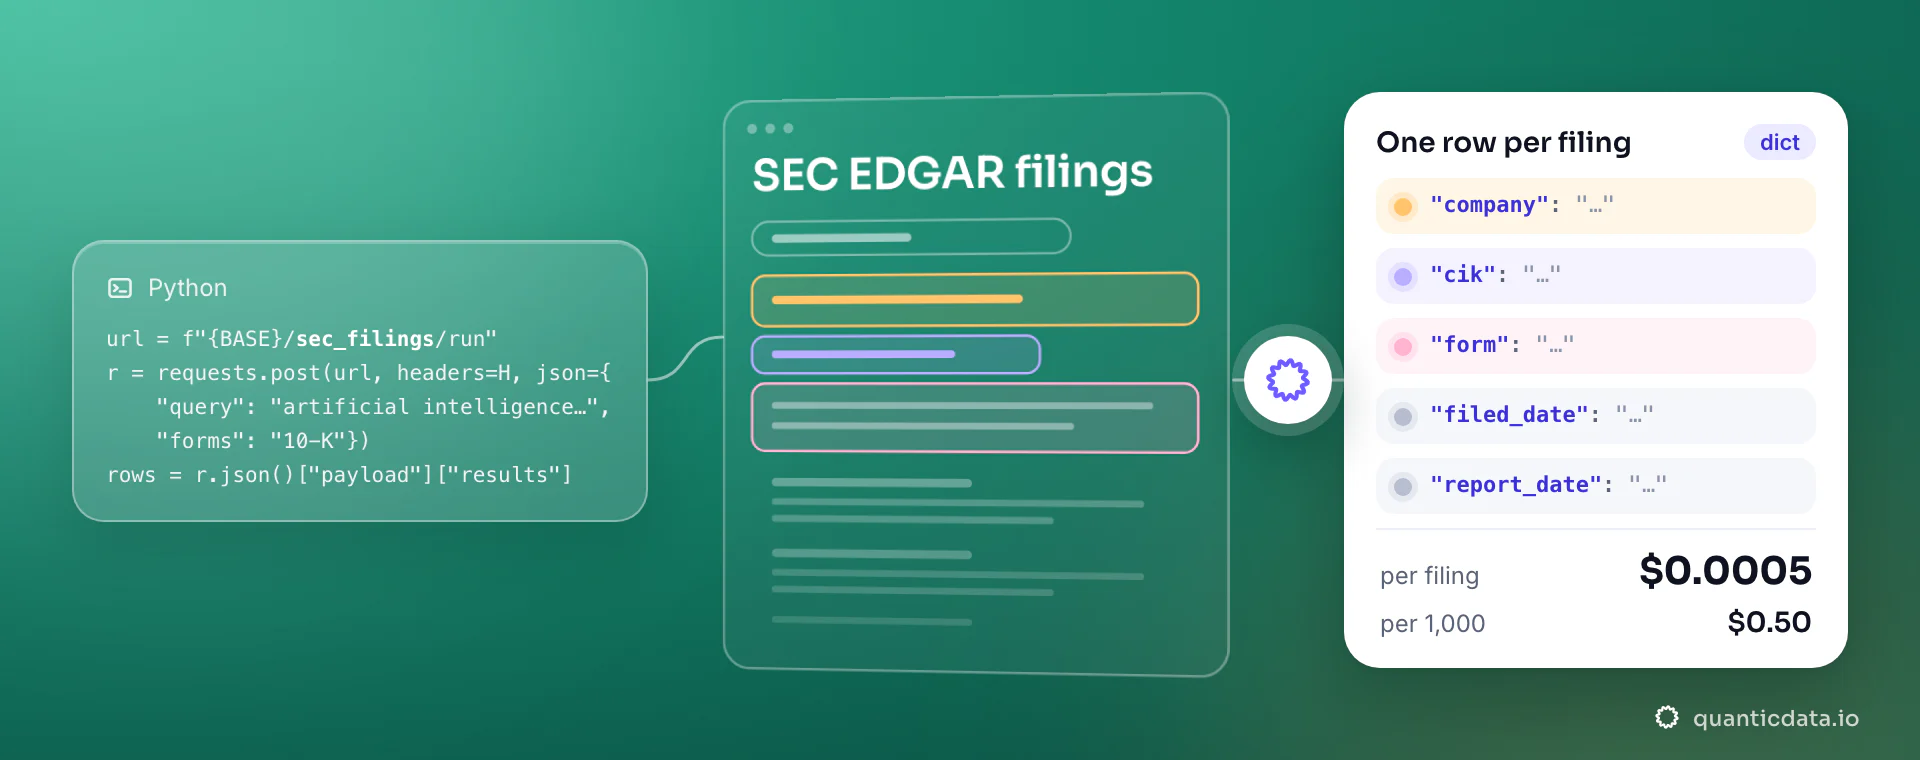
SEC filings — full-text search across all filings, or one company's filing history. One POST from Python with the input, rows back as JSON with 24 fields, $0.0005 per delivered filing. No proxies or parsers to maintain.
First call
Install, call, read the rows.
pip install requestsimport os, requests
r = requests.post(
"https://api.quanticdata.io/v1/scraper/collectors/sec_filings/run",
headers={"Authorization": f"Bearer {os.environ['QD_API_KEY']}"},
json={
"query": "artificial intelligence risk factors",
"forms": "10-K",
"max_results": 20,
},
timeout=120,
)
r.raise_for_status()
run = r.json()["payload"]
print(run["count"], "rows,", run["cost"]["usd"], "USD")
for row in run["results"]:
print(row.get("company"), row.get("cik"), row.get("form"), row.get("filed_date"))The key comes from an environment variable, never from the code. The run answers in the same request when it finishes in time; payload.results holds the rows and payload.cost what they cost.
Request parameters
What the collector takes.
| Parameter | Type | Required | Meaning |
|---|---|---|---|
query | string | no | Full-text search across all filings. Use this OR ticker/cik. |
ticker | string | no | Company ticker — resolved to its CIK. Use with company mode. |
cik | string | no | SEC Central Index Key (numeric). Alternative to ticker. |
forms | string | no | Filter to a form type, e.g. 10-K, 8-K, S-1. |
date_from | string | no | Earliest filing date, YYYY-MM-DD. |
date_to | string | no | Latest filing date, YYYY-MM-DD. |
max_results | integer | no (default 20) | How many filings to deliver at most (1–100). You pay only for delivered filings. |
Response fields
24 fields per filing.
| Field | Type | What it holds |
|---|---|---|
rank | integer | 1-based position. |
company | string, nullable | Filer name. |
cik | string, nullable | SEC CIK. |
form | string, nullable | Form type (10-K, 8-K…). |
filed_date | string, nullable | Filing date. |
report_date | string, nullable | Period of report (company mode). |
file_type | string, nullable | Document type (search mode). |
description | string, nullable | Document description (search mode). |
accession | string, nullable | Accession number. |
is_xbrl | boolean, nullable | Whether the filing has XBRL data (company mode). |
url | string, nullable | Direct link to the filing document. |
company_name | string, nullable | Filer name without the ticker/CIK suffix. |
ticker | string, nullable | Ticker, when the filer has one. |
items | string[] | 8-K item numbers the filing reports (e.g. 2.02, 9.01). |
file_number | string, nullable | SEC file number. |
accepted_at | string, nullable | Acceptance timestamp (company mode). |
primary_doc_description | string, nullable | Primary document description (company mode). |
is_inline_xbrl | boolean, nullable | Whether the filing is Inline XBRL (company mode). |
size | integer, nullable | Filing size in bytes (company mode). |
sic | string, nullable | Standard Industrial Classification code. |
state | string, nullable | State of the business address. |
location | string, nullable | City of the business address (search mode). |
inc_state | string, nullable | State or country of incorporation (search mode). |
index_url | string, nullable | Filing index page listing every document and exhibit. |
Add ?format=csv to the runs endpoint to get the same rows as CSV.
Long runs
Run in the background, then poll.
A run that needs more time can go to the background: send "async": true, get 202 with the run id, and poll the runs endpoint until the status is done. Reading a run is free.
import os, time, requests

H = {"Authorization": f"Bearer {os.environ['QD_API_KEY']}"}
r = requests.post("https://api.quanticdata.io/v1/scraper/collectors/sec_filings/run", headers=H,
                  json={**{"query":"artificial intelligence risk factors","forms":"10-K","max_results":20}, "async": True}, timeout=30)
run_id = r.json()["payload"]["run_id"]
while True:
    run = requests.get(f"https://api.quanticdata.io/v1/scraper/collectors/runs/{run_id}", headers=H, timeout=30).json()["payload"]
    if run["status"] in ("done", "failed"):
        break
    time.sleep(5)
print(run["status"], run["count"])Errors
What can come back, and what is billed.
| Status | Meaning | Billed |
|---|---|---|
400 | The input does not match the collector (payload.errors) | No |
401 | Missing or wrong API key | No |
402 | Balance and free credit do not cover the run: top up | No |
422 | The input can never resolve; retrying the same input cannot help | No |
424 | The run failed at the source (blocked, timed out, layout changed); safe to retry | No |
429 | Rate limit or a per-account brake; wait for Retry-After | No |
Only delivered rows are billed: a run that delivers nothing costs nothing.
Price
$0.0005 per delivered filing.
| Rows | Cost |
|---|---|
| 1 | $0.0005 |
| 1,000 | $0.50 |
| 10,000 | $5.00 |
Up to 100 filings per run; split larger jobs into several runs. The $2 free credit every month covers about 4,000 filings. No subscription; paid tiers lower the unit price. All collector prices: collector pricing.
Before you run it
Questions developers ask
Is there a free SEC EDGAR filings API?
Every account gets $2 of free usage each month, about 4,000 filings of this collector at $0.0005 each, with no card.
Do I have to handle proxies, retries or blocks?
No. The collector runs on our network and handles them; a run blocked at the source returns 424 and is not billed.
How many rows can one run return?
Up to 100 filings per run (the max_results input, where the collector has one).
Can an AI agent run it?
Yes: the MCP server exposes it as the run_collector tool, with the same input and price. See the MCP server.
Run it on the free credit.
Create an API key, export it as QD_API_KEY and run the example. $0.0005 per delivered filing, no subscription.