Collectors · Knowledge & reference
Coursera Scraper API in Python
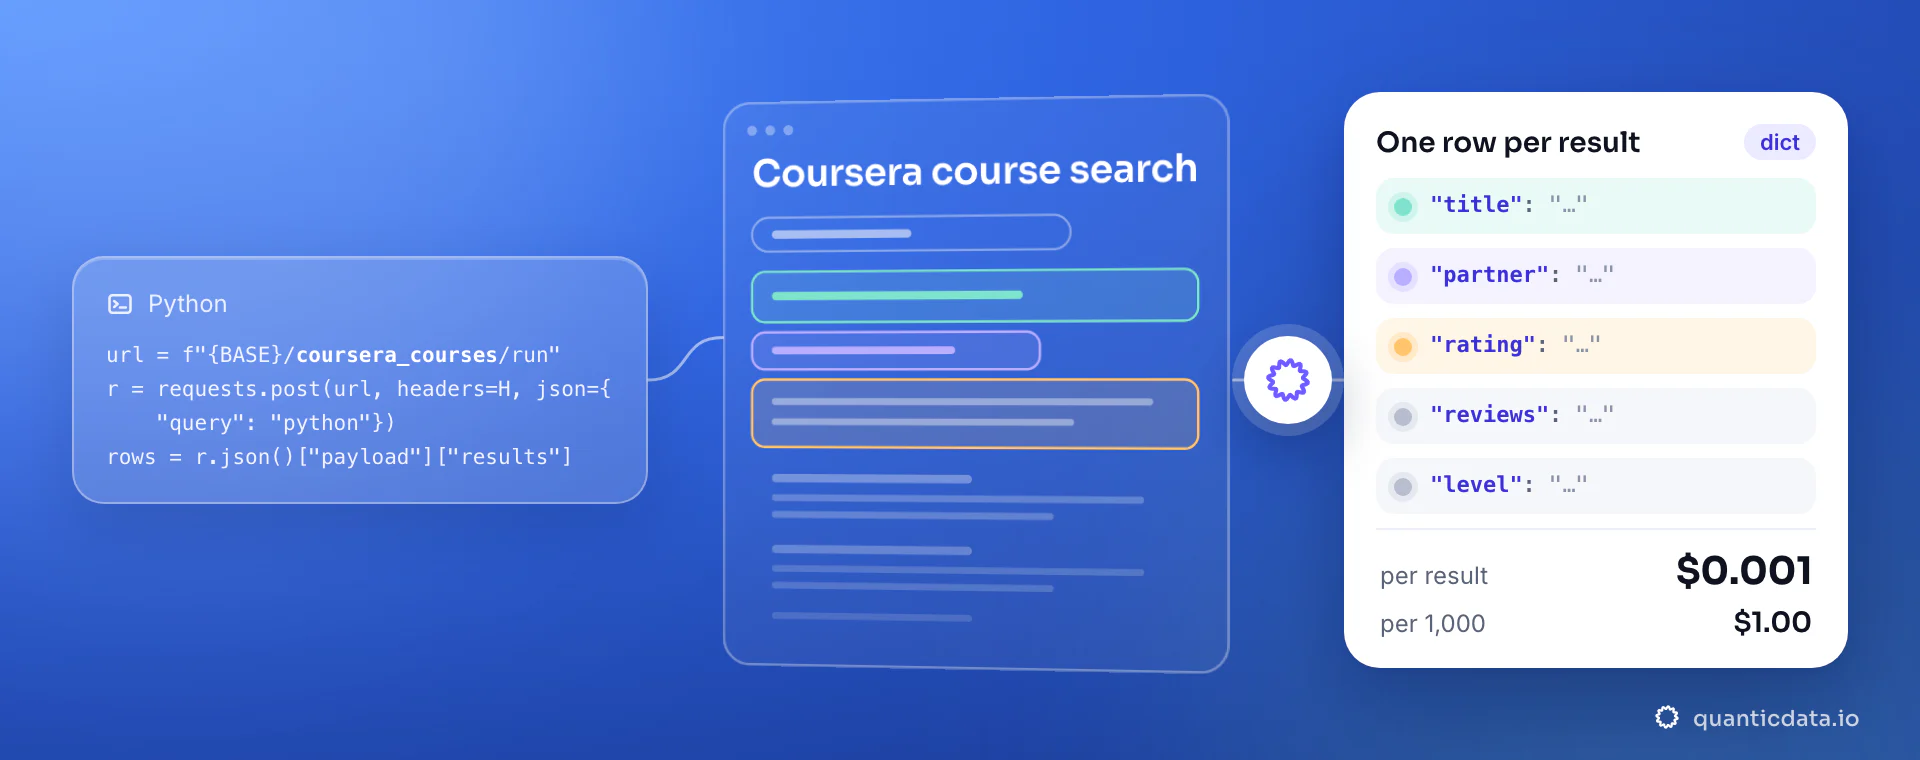
Search Coursera by keyword — partner, rating, review count, level and duration per course. One POST from Python with query, rows back as JSON with 17 fields, $0.001 per delivered result. No proxies or parsers to maintain.
First call
Install, call, read the rows.
pip install requestsimport os, requests
r = requests.post(
"https://api.quanticdata.io/v1/scraper/collectors/coursera_courses/run",
headers={"Authorization": f"Bearer {os.environ['QD_API_KEY']}"},
json={
"query": "python",
"max_results": 12,
},
timeout=120,
)
r.raise_for_status()
run = r.json()["payload"]
print(run["count"], "rows,", run["cost"]["usd"], "USD")
for row in run["results"]:
print(row.get("id"), row.get("title"), row.get("partner"), row.get("partners"))The key comes from an environment variable, never from the code. The run answers in the same request when it finishes in time; payload.results holds the rows and payload.cost what they cost.
Request parameters
What the collector takes.
| Parameter | Type | Required | Meaning |
|---|---|---|---|
query | string | yes | What to search Coursera for — a topic, technology or skill. |
level | string: Beginner, Intermediate, Advanced, Mixed | no | Restrict to one difficulty level. Coursera's own filter values. |
product_type | string: Courses, Specializations, Guided Projects, Professional Certificates, Projects, Degrees | no | Restrict to one kind of product. Coursera's own filter values — use "Courses" to exclude degrees and certificates. |
country | string | no | ISO 3166-1 alpha-2 code for the proxy exit (default us). |
max_results | integer | no (default 12) | How many results to deliver at most (1–60). You pay only for delivered results. |
Response fields
17 fields per result.
| Field | Type | What it holds |
|---|---|---|
rank | integer | 1-based position in the delivered set, in Coursera's own result order. |
id | string, nullable | Coursera's typed product id, e.g. "course~ejOz7RDUEei99hK0xs-tsg" or "s12n~F-h1g0w7EeWeOApO_l5R1w" — the stable de-duplication key. |
title | string, nullable | Course, specialization or degree title. |
partner | string, nullable | First listed partner — the university or company offering it. |
partners | string[] | Every listed partner, in Coursera's order (co-branded programmes carry more than one). |
rating | number, nullable | Average rating out of 5, to 2 decimals. Null on products Coursera has never rated, such as degrees. |
reviews | integer, nullable | Exact number of ratings the average is based on — the site's cards round this to "44K". |
level | string, nullable | Difficulty as the card states it: Beginner, Intermediate, Advanced or Mixed. Null on degrees, which state none. |
duration | string, nullable | Time commitment as the card states it, e.g. "1 - 3 Months", "Less Than 2 Hours", "1 - 4 Years". |
product_type | string, nullable | What kind of product this is: Course, Specialization, Professional Certificate, Guided Project, Project or Degree. |
url | string, nullable | Absolute URL of the product page. |
image | string, nullable | Course artwork URL. |
skills | string[] | Skills Coursera lists for this product. |
sponsored | boolean | True when Coursera marks the row as a paid placement. These are mixed into the ranked list, so a sponsored row's rank is a bought slot, not a relevance position. |
is_free | boolean | True when Coursera marks the course itself as free. |
in_coursera_plus | boolean | True when the product is included in a Coursera Plus subscription. |
is_new | boolean | True when Coursera flags the product as new content. |
Add ?format=csv to the runs endpoint to get the same rows as CSV.
Long runs
Run in the background, then poll.
A run that needs more time can go to the background: send "async": true, get 202 with the run id, and poll the runs endpoint until the status is done. Reading a run is free.
import os, time, requests

H = {"Authorization": f"Bearer {os.environ['QD_API_KEY']}"}
r = requests.post("https://api.quanticdata.io/v1/scraper/collectors/coursera_courses/run", headers=H,
                  json={**{"query":"python","max_results":12}, "async": True}, timeout=30)
run_id = r.json()["payload"]["run_id"]
while True:
    run = requests.get(f"https://api.quanticdata.io/v1/scraper/collectors/runs/{run_id}", headers=H, timeout=30).json()["payload"]
    if run["status"] in ("done", "failed"):
        break
    time.sleep(5)
print(run["status"], run["count"])Errors
What can come back, and what is billed.
| Status | Meaning | Billed |
|---|---|---|
400 | The input does not match the collector (payload.errors) | No |
401 | Missing or wrong API key | No |
402 | Balance and free credit do not cover the run: top up | No |
422 | The input can never resolve; retrying the same input cannot help | No |
424 | The run failed at the source (blocked, timed out, layout changed); safe to retry | No |
429 | Rate limit or a per-account brake; wait for Retry-After | No |
Only delivered rows are billed: a run that delivers nothing costs nothing.
Price
$0.001 per delivered result.
| Rows | Cost |
|---|---|
| 1 | $0.001 |
| 1,000 | $1.00 |
| 10,000 | $10.00 |
Up to 60 results per run; split larger jobs into several runs. The $2 free credit every month covers about 2,000 results. No subscription; paid tiers lower the unit price. All collector prices: collector pricing.
Before you run it
Questions developers ask
Is there a free Coursera course search API?
Every account gets $2 of free usage each month, about 2,000 results of this collector at $0.001 each, with no card.
Do I have to handle proxies, retries or blocks?
No. The collector runs on our network and handles them; a run blocked at the source returns 424 and is not billed.
How many rows can one run return?
Up to 60 results per run (the max_results input, where the collector has one).
Can an AI agent run it?
Yes: the MCP server exposes it as the run_collector tool, with the same input and price. See the MCP server.
Run it on the free credit.
Create an API key, export it as QD_API_KEY and run the example. $0.001 per delivered result, no subscription.