Collectors · Company data
Capterra Scraper API in Python
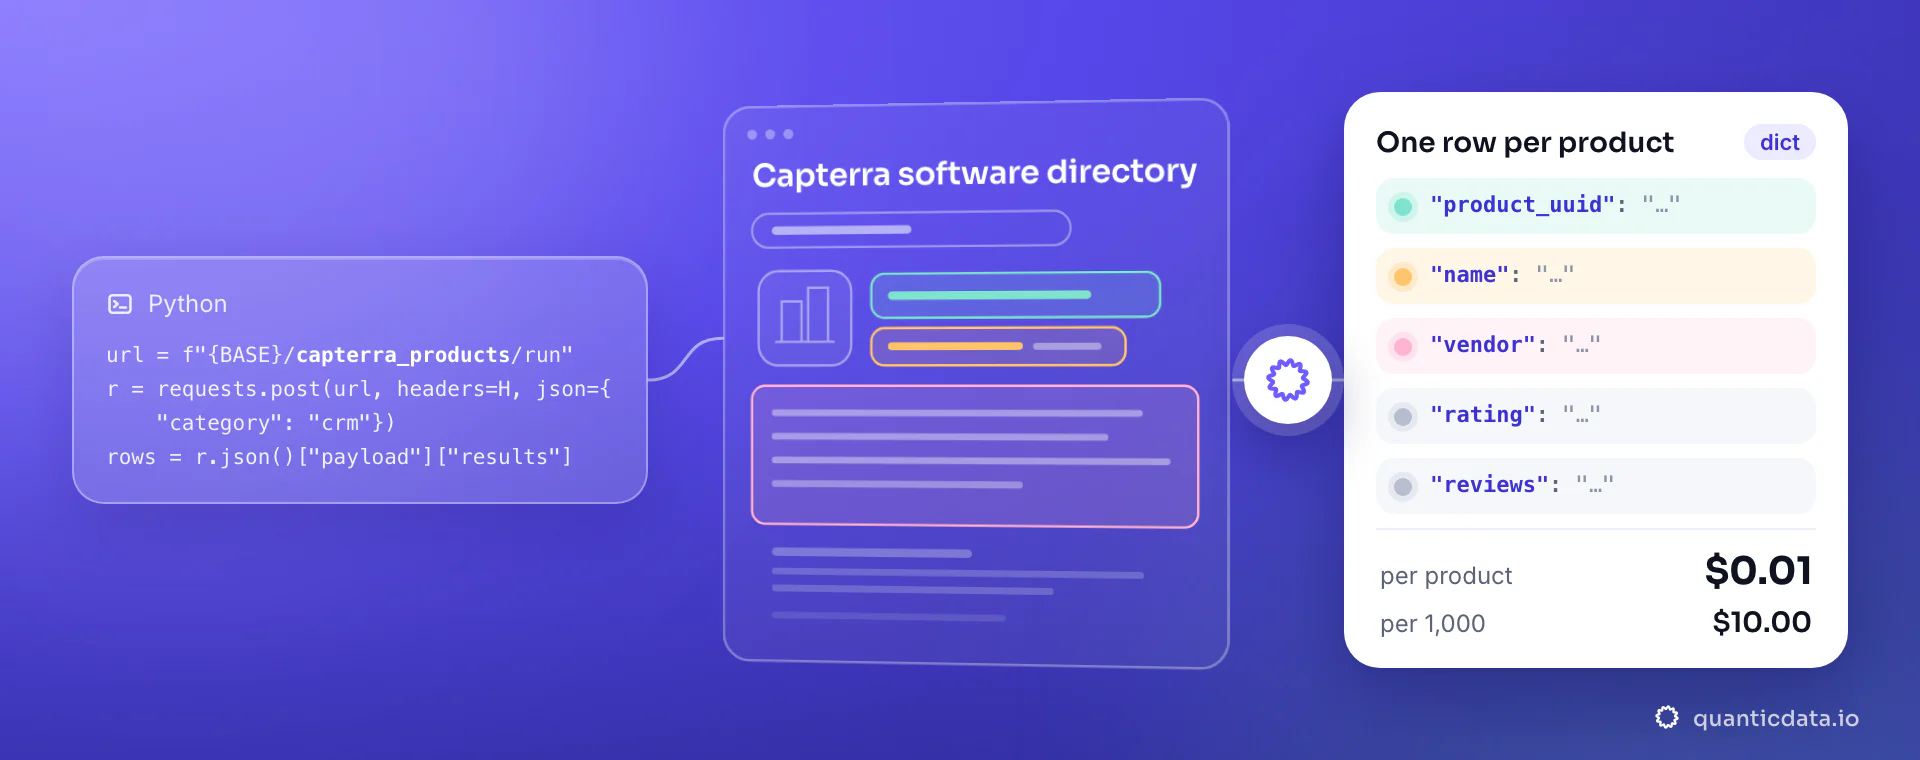
Software products from a Capterra category — vendor, rating, review breakdown, pricing and paid-placement flag. One POST from Python with category, rows back as JSON with 34 fields, $0.01 per delivered product. No proxies or parsers to maintain.
First call
Install, call, read the rows.
pip install requestsimport os, requests
r = requests.post(
"https://api.quanticdata.io/v1/scraper/collectors/capterra_products/run",
headers={"Authorization": f"Bearer {os.environ['QD_API_KEY']}"},
json={
"category": "crm",
"max_results": 50,
},
timeout=120,
)
r.raise_for_status()
run = r.json()["payload"]
print(run["count"], "rows,", run["cost"]["usd"], "USD")
for row in run["results"]:
print(row.get("product_id"), row.get("product_uuid"), row.get("name"), row.get("vendor"))The key comes from an environment variable, never from the code. The run answers in the same request when it finishes in time; payload.results holds the rows and payload.cost what they cost.
Request parameters
What the collector takes.
| Parameter | Type | Required | Meaning |
|---|---|---|---|
category | string | yes | The software category to list, as a plain keyword — "crm", "project management", "help desk", "accounting". Matched against Capterra's own category index, where an exact name wins over the categories that merely contain it ("crm" resolves to CRM, not Construction CRM). A Capterra slug or category URL is accepted too and skips the lookup fetch. |
country | string | no | ISO 3166-1 alpha-2 code — proxy exit geo and Google locale (gl). Omit for the default pool. |
max_results | integer | no (default 25) | How many products to deliver at most (1–500). You pay only for delivered products. |
Response fields
34 fields per product.
| Field | Type | What it holds |
|---|---|---|
rank | integer | Position in Capterra's own order for this response, counting across pages. Note this order is bid-driven, not merit-driven — see `sponsored`. |
product_id | integer | Capterra's numeric product id (its `seoId`, the number in the product URL). Stable, and the key used to de-duplicate. |
product_uuid | string, nullable | Capterra's internal product UUID. |
name | string | Product name. |
vendor | string, nullable | Company behind the product, e.g. "Oracle" for NetSuite. Published in Capterra's data layer only — it does not appear anywhere in the rendered listing card. |
rating | number, nullable | Overall star rating out of 5, rounded to 2 decimals. Capterra publishes it at raw float precision (4.233430091920658) and prints it as 4.2. |
reviews | integer, nullable | Total number of reviews. 1 is a real value and is kept — several listed products have a single 5.0 review. |
rating_breakdown | object, nullable | Star histogram as {"1":n,…,"5":n}, keyed by star value. Capterra emits these buckets unordered and omits a star nobody awarded. |
ease_of_use | number, nullable | Capterra's "Ease of Use" sub-score out of 5, rounded to 2 decimals. |
customer_service | number, nullable | Capterra's "Customer Service" sub-score out of 5, rounded to 2 decimals. |
functionality | number, nullable | Capterra's "Features" / functionality sub-score out of 5, rounded to 2 decimals. |
value_for_money | number, nullable | Capterra's "Value for Money" sub-score out of 5, rounded to 2 decimals. |
likelihood_to_recommend | number, nullable | Likelihood to recommend as the 0–1 fraction Capterra publishes (0.63 = the 63% its UI shows). |
description | string, nullable | The short product description Capterra shows on the listing card. |
category | string, nullable | The category being listed, e.g. "CRM Software", read from the page breadcrumb. |
category_id | string, nullable | Capterra's internal UUID for the category. |
starting_price | number, nullable | Starting price of the default plan, in `price_currency`. Null where Capterra publishes no pricing plan — which is the case for every sponsored row, so expect nulls across the first page. |
price_currency | string, nullable | Currency of `starting_price`. Capterra doubles its symbol in the payload ("$$"); an exactly repeated symbol is collapsed back to one. |
pricing_plans | integer, nullable | How many pricing plans Capterra lists for the product. Null when it publishes none. |
has_free_trial | boolean, nullable | Whether Capterra flags a free trial. |
has_free_version | boolean, nullable | Whether Capterra flags a free version. |
sponsored | boolean | True when the row is a paid placement. Capterra orders its directories by bid, so this is how to tell an advertisement from an organic listing. |
bid_spot | integer, nullable | The advertising slot the vendor paid for (1 = top). Null on organic rows. |
logo | string, nullable | Product logo image URL. |
slug | string, nullable | Capterra's URL slug for the product. |
url | string, nullable | Capterra product page URL. |
reviews_url | string, nullable | Capterra reviews page URL, only when the product actually publishes one. |
long_description | string, nullable | The product's full description, when the listing carries one. |
features | string[], nullable | Feature names Capterra lists for the product. |
reviews_small_business | integer, nullable | Reviews written by small businesses. |
reviews_mid_size | integer, nullable | Reviews written by mid-size businesses. |
reviews_enterprise | integer, nullable | Reviews written by enterprises. |
reviews_last_6_months | integer, nullable | Reviews published in the last 6 months. |
reviews_last_12_months | integer, nullable | Reviews published in the last 12 months. |
Add ?format=csv to the runs endpoint to get the same rows as CSV.
Long runs
Run in the background, then poll.
A run that needs more time can go to the background: send "async": true, get 202 with the run id, and poll the runs endpoint until the status is done. Reading a run is free.
import os, time, requests

H = {"Authorization": f"Bearer {os.environ['QD_API_KEY']}"}
r = requests.post("https://api.quanticdata.io/v1/scraper/collectors/capterra_products/run", headers=H,
                  json={**{"category":"crm","max_results":50}, "async": True}, timeout=30)
run_id = r.json()["payload"]["run_id"]
while True:
    run = requests.get(f"https://api.quanticdata.io/v1/scraper/collectors/runs/{run_id}", headers=H, timeout=30).json()["payload"]
    if run["status"] in ("done", "failed"):
        break
    time.sleep(5)
print(run["status"], run["count"])Errors
What can come back, and what is billed.
| Status | Meaning | Billed |
|---|---|---|
400 | The input does not match the collector (payload.errors) | No |
401 | Missing or wrong API key | No |
402 | Balance and free credit do not cover the run: top up | No |
422 | The input can never resolve; retrying the same input cannot help | No |
424 | The run failed at the source (blocked, timed out, layout changed); safe to retry | No |
429 | Rate limit or a per-account brake; wait for Retry-After | No |
Only delivered rows are billed: a run that delivers nothing costs nothing.
Price
$0.01 per delivered product.
| Rows | Cost |
|---|---|
| 1 | $0.01 |
| 1,000 | $10.00 |
| 10,000 | $100.00 |
Up to 500 products per run; split larger jobs into several runs. The $2 free credit every month covers about 200 products. No subscription; paid tiers lower the unit price. All collector prices: collector pricing.
Before you run it
Questions developers ask
Is there a free Capterra software directory API?
Every account gets $2 of free usage each month, about 200 products of this collector at $0.01 each, with no card.
Do I have to handle proxies, retries or blocks?
No. The collector runs on our network and handles them; a run blocked at the source returns 424 and is not billed.
How many rows can one run return?
Up to 500 products per run (the max_results input, where the collector has one).
Can an AI agent run it?
Yes: the MCP server exposes it as the run_collector tool, with the same input and price. See the MCP server.
Run it on the free credit.
Create an API key, export it as QD_API_KEY and run the example. $0.01 per delivered product, no subscription.